Why doesn’t AI mention your brand?
Two failures look identical from outside: engines can’t read your pages,
or they read them and never cite you. The free scan checks both.
Free · No account · No email · 40 published checks See a full sample report (vercel.com) → What it does / does not do
- CrawlabilityPASS
- Citation readinessPASS
- ChatGPT
- Gemini
- Claude
- Perplexity
- No AI crawler is blockedpass
- An entity node is declaredpass
- Entity is cross-referencedpass
- Headings are phrased as real questionspass
- External authoritative sources are citedpass
- A markdown alternate is declaredpass
- A machine-readable date is present and recentpass
- Alternate language versions are declaredpass
Two failures that look the same from the outside.
It cannot read you
robots.txt turns the crawler away, a firewall refuses it, or the page is rendered by JavaScript the crawler never runs. If that is the case, nothing else on the page matters: there is no path from the page to an answer.
It reads you, and cites someone else
The crawler gets in, but the answer names a competitor and links to a source you do not control. That is not a crawling problem - it is an entity and evidence problem.
Not sure which one you have? Start with the free scan. It tells you whether the first problem is real, and the report names every rule it checked, so a second opinion costs you nothing.
What a paid report looks like
The scan above reads your pages. The report asks an AI engine your buyers' questions and records what it said. This is the shape of that document.
AI visibility measurement — sample report
Readiness — sample scan of vercel.com
The free scan produces the ring and the profile below. The paid report adds the engine answers underneath.
| Dimension | Score |
|---|---|
| AI Crawler Access | 94 |
| Machine Readability | 100 |
| Content Depth | 73 |
| Citability & Evidence | 45 |
| Answer Readiness | 50 |
| Trust & Authority | 100 |
| Semantic Structure | 100 |
| Metadata & Discoverability | 86 |
| AI Context Files | 83 |
| Freshness | 0 |
| International Readiness | 100 |
| Delivery & Mobile | 50 |
Question bank (excerpt)
- What tools help a small team track AI search visibility?
- Is Northwind Labs worth paying for compared with a spreadsheet?
- How do I measure whether ChatGPT mentions my brand?
Per-question counts
| Question | Mentioned Northwind | Named instead |
|---|---|---|
| Q1 | 2 of 3 | G2, Reddit, a competitor blog |
| Q2 | 0 of 3 | Two named competitors |
| Q3 | 1 of 3 | Capterra, YouTube |
| Q4 | 3 of 3 | — |
| … 25 more questions | … | … |
Raw answer (excerpt)
“…for a small team, the practical options are a spreadsheet with a fixed question set, or a tool that runs the questions for you. Northwind Labs is one of the tools that does this; it is not the cheapest, and for a single brand the spreadsheet is usually enough to start…”
Share of voice (demo)
Citation graph (demo)
Cited domains by frequency
- g2.com — 14 citations
- reddit.com — 9 citations
- a competitor’s comparison page — 7 citations
- your own domain — 3 citations
The full report adds every answer verbatim, the facts the answers asserted, and an action list read off the counts. The data workbook carries one row per run so any number can be traced back to the answer it came from.
This is a sample. Your report uses your brand, your questions and your engines.
Readiness gets you quoted. Visibility tells you whether you were.
The free scan measures the page. The paid report asks your buyers’ questions to ChatGPT, Gemini, Claude and Perplexity, then counts how often you were named, who was named instead, and which domains the answers cited.
Visibility over time
weekly · mention rateCompetitor ranking
this month- #1northwindlabs.comyou3684127%
- #2rivala.io166017%
- #3bluepeak.com126015%
- #4quarrymetrics.com101014%
- #5signalcraft.io71013%
- #6beaconlabs.ai61010%
- #7trellis.so000%
Cited domains
- youtube.com13730%
- reddit.com11926%
- g2.com8018%
- capterra.com7517%
- northwindlabs.com419%
Owned vs third-party
- Your domain5%
- Third-party sources95%
Platform distribution
- ChatGPT27634%
- Gemini21126%
- Claude14618%
- Perplexity11414%
- Grok658%
The people who have to explain the number.
Run a fresh scan
The report is generated from the site when you open it. Its results can change between runs, so this preview shows the dated self-audit record instead of an undated capture.
Open live report →- 40checkspublished, and the ones this site scores itself on
- 12dimensionsweighted, in the order they are published
- 100pointsadded up. The heaviest is 16, for whether a crawler can read the page at all
- 30sitesscanned for the published study, and every row is downloadable
- 9 of 30blockedof those sites disallow the AI crawlers this scanner tracks
- 6 of 6news publishersof the ones measured turn every tracked AI crawler away
- 22 of 30unbounddeclare no Organization or WebSite entity for a model to attach a name to
- 9use sameAsof the 30, which is the cheapest way to bind a brand to one entity
We scored 1,000 AI-tool homepages. The median is 53/100.
620 returned a normal page and were scored with the same 40 checks this scanner runs. 59% graded F, 62% carry no Organization entity markup, and 48 of 620 block at least one AI crawler. The full ranking, the CSV and the method are published.
Three questions decide whether you get quoted.
AI Crawler Passability
Reads robots.txt and reports which of GPTBot, PerplexityBot and ClaudeBot are disallowed at your root.
How to allow AI crawlers →Entity & Structured Data
Reads your JSON-LD and reports whether Organization, WebSite and sameAs bind your brand to one entity rather than three loose strings.
Schema.org for GEO →Dynamic Score Badge
Embed a badge carrying your verified GEO score in your GitHub README or site footer.
Get the badge →Three free tools. No account, no limit.
The audit report
Forty published checks across twelve weighted dimensions. Every dimension shows its own score and the evidence behind it, and every failure names the rule it broke.
Open a live report →100/100
The /llms.txt studio
Enter a domain and the studio reads the homepage, then drafts an llms.txt from the real page title, the description and the internal links it actually found.
Generate a file →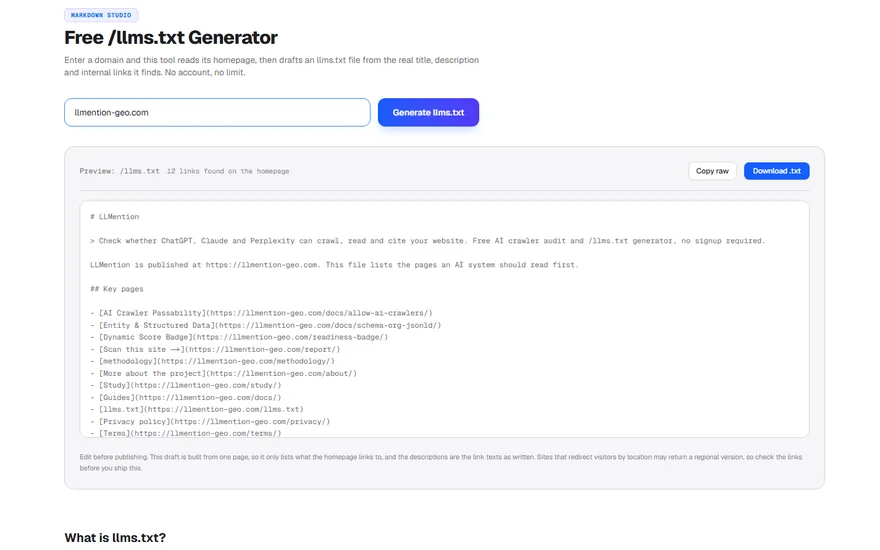
The readiness badge
A badge carrying the score from a real scan, in Markdown for a README or HTML for a footer. The number is read from the scan and cannot be typed in.
Get the badge →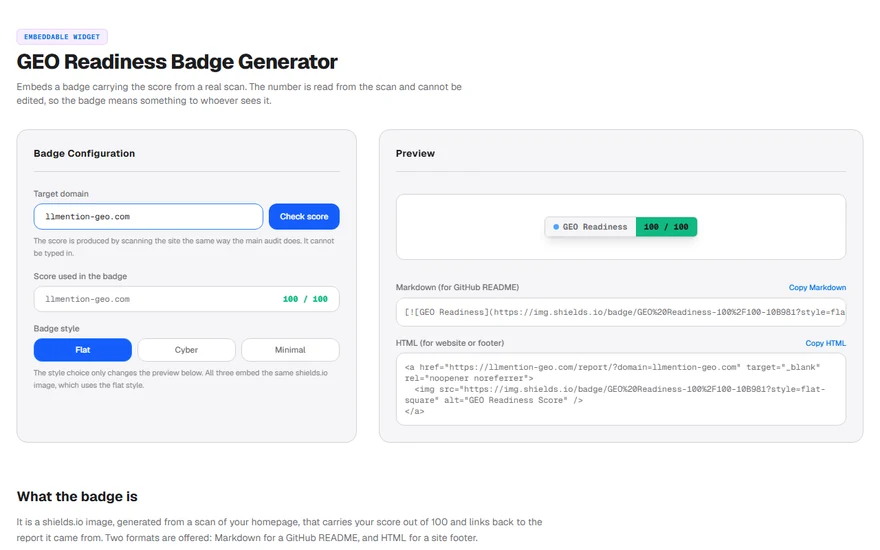
This site is measured by the same 40 checks
LLMention audits its own homepage with the rules it applies to yours, and links the result rather than quoting a number you have to take on trust. Measured on 9 November 2026: 100 out of 100, grade A, 40 of 40 checks passing. The hreflang rule passes because this site now publishes the homepage and the pricing page in five additional languages, each linked to the others; until October 2026 the site was English-only and that rule could not judge it, and the change is recorded on the methodology page. The markdown twin this page used to lack is generated at /markdown/ from the same content the page renders, so it cannot drift from it. A 100 here is a claim about the method, not about us — run the scan yourself and the report shows all twelve dimension scores, the evidence behind every check, and every rule this site fails at the moment you looked.
Twelve dimensions, not one mystery number.
A score you cannot interrogate is a score you cannot act on. Each dimension carries a published share of the total, and every rule inside it is listed on the methodology page.
- AI Crawler Access
- 16% of the score
- Machine Readability
- 12% of the score
- Content Depth
- 11% of the score
- Citability & Evidence
- 11% of the score
- Answer Readiness
- 10% of the score
- Trust & Authority
- 10% of the score
- Semantic Structure
- 8% of the score
- Metadata & Discoverability
- 7% of the score
- AI Context Files
- 5% of the score
- Freshness
- 5% of the score
- International Readiness
- 3% of the score
- Delivery & Mobile
- 2% of the score
Full weights, every rule and what the score cannot tell you: methodology
From URL to a fix list in one pass.
No account, no crawler of your own to install, nothing to configure. The scan runs live against your origin and returns the rules you fail, with the reason.
- 1
Enter a domain
Root domain or full URL. The scanner resolves the origin and fetches robots.txt, the page itself, llms.txt and the sitemap, and reads the Last-Modified header.
- 2
40 explicit checks run
Twelve weighted dimensions, from crawler access and entity markup to answer readiness, evidence and citability. Every rule and its weight is published.
- 3
You get the fix list
Each failure names the rule, shows what the scanner actually saw, and links the guide that fixes it. Nothing is cached; re-run any time.
The target moved from a rank to a cited passage.
| Dimension | Traditional SEO | Generative GEO |
|---|---|---|
| What you win | A ranking position on a results page | A sentence quoted inside a generated answer |
| Unit of competition | The page, ranked against other pages | The passage, retrieved against other passages |
| Main lever | Keywords, backlinks, page authority | Entity clarity, evidence, extractable structure |
| How you verify it | Rank tracking and click-through rate | Whether a model repeats your claim, and cites you |
| Failure mode | Position 11, no clicks | The answer is given, and you are not in it |
The measured gains come from what a page says and cites.
up to 40%
The paper's own headline for visibility gains in generative engine responses.
41%
Best tested method over the no-optimization baseline, position-adjusted word count (Table 1).
28%
The same comparison on subjective impression (Table 1).
GEO can boost visibility by up to 40% overall in generative engine responses, and in the paper’s Table 1 the best of the tested methods improve on the no-optimization baseline by 41% and 28%.
LLMention weights its score accordingly. Citability and evidence carry 11% of the total and answer readiness a further 10%, because those are the dimensions tied most directly to the measurements above. The full weighting, every rule, and an explicit account of what the score cannot tell you are published at methodology.
- Generative Engine Optimization — KDD 2024. The source of the figures quoted above.
- What Generative Search Engines Like — which page characteristics are actually surfaced in generated answers.
- The llms.txt convention — read the primary source rather than a vendor summary of it.
Straight answers about GEO
Short, direct answers about GEO and AI crawler access.
What is Generative Engine Optimization (GEO)?
+
GEO is the practice of making a website discoverable, parseable and citable by AI search engines such as ChatGPT, Perplexity, Claude and Google AI Overviews. Instead of ranking a blue link, the goal is to be quoted inside a generated answer.
How do I check whether AI crawlers can read my website?
+
Check your robots.txt for rules that block AI crawler user-agents such as GPTBot, ClaudeBot, PerplexityBot and Bytespider. LLMention reads robots.txt automatically and names exactly which of them are disallowed at your root. It cannot see your firewall rules — a request it makes comes from its own address, so check those in your CDN yourself.
Does LLMention tell me whether ChatGPT mentions my brand?
+
The free scanner does not: it measures whether your pages are in a state that makes being cited possible — crawler access, structure, markup, evidence — and it never queries an engine. The paid audit does ask: 25–30 questions your buyers actually ask are put to the engines, each run three times in a fresh session, and every answer is recorded so the mentions can be counted. If what you want is a mention count, that is the paid product; if you want to know whether the engine can read you at all, start with the free scan.
Why doesn't ChatGPT mention my company?
+
There are two common causes, and they need different fixes. Either the crawler cannot get to the page at all — robots.txt, a firewall that refuses it, a client-rendered page with no server HTML — or it reads the page and finds nothing specific enough to quote: no clear entity, no extractable answer, no cited evidence. The free scan finds the first cause in about 30 seconds. The second is what the paid audit measures, by asking the engines the questions your buyers ask and recording which brands and domains the answers contain.
Do I need an llms.txt file?
+
Not necessarily. llms.txt is an emerging convention rather than a standard: no crawler documentation we could open commits to reading it — OpenAI's help centre and Anthropic's crawler article both specify robots.txt instead. It is cheap to add and it does help documentation sites and coding agents, but treat it as one small signal, not a ranking factor.
Which AI crawlers should I allow in robots.txt?
+
Allow the crawlers behind the engines you want citations from: GPTBot and OAI-SearchBot for OpenAI, ClaudeBot and Claude-SearchBot for Anthropic, PerplexityBot for Perplexity, Google-Extended for Google, and Bingbot, whose index also feeds ChatGPT search. Blocking a crawler removes you from that engine's answers entirely.
Is GEO replacing SEO?
+
No. GEO and SEO share most of their foundations: crawlable pages, clear structure, accurate facts and genuine authority. GEO adds an emphasis on answer-shaped content, entity markup such as Schema.org JSON-LD, and machine-readable context files. A site that already does SEO well starts GEO from a strong position.
About LLMention
LLMention is an independent tool. The free scanner audits whether AI search engines can reach, parse and cite a website — it never asks an engine about your brand. The paid audit measures the other half: 25–30 questions your buyers ask are put to the engines, each run three times, and every answer is recorded so the mentions can be counted. Neither is a ranking tracker: no position is measured and no traffic is predicted. It is not affiliated with OpenAI, Anthropic, Google or Perplexity, and it holds no data relationship with them. Nor is it connected to DataForSEO’s LLM Mentions API (llm.dataforseo.com), a different product whose name is close enough to be confused with this one. The scanner and the llms.txt generator are free and require no account.
The project publishes its scoring method in full, including the checks it runs, the weight each one carries, and the parts of the picture it cannot see. No score floor is applied, so a page that satisfies none of the checks scores near zero. Signals with weak evidence behind them are weighted low rather than advertised as ranking factors.
Written and maintained by Alex Xu, the person accountable for the measurements. More about the project, or get in touch if the scanner reports something you believe is wrong.
Find out what the models see when they look at you.
Free, no account, and the same 40 checks this site runs on itself.
This site scores 100 / 100 on its own scanner, self-measured on 9 November 2026 — see the report.